Revenue and EBIT estimates in the DACH private market
How to correctly interpret ProxDeal’s revenue and EBIT estimates for private DACH companies and use them for M&A and market analysis.

Contents
- Why structural reporting rules make estimates necessary
- How does ProxDeal reliably assess a company’s actual size and EBIT?
- Modelling with machine learning
- Meaningful ranges instead of single values without context
- The confidence score – how useful is the estimate?
- Interpretation – how to read the estimates correctly
- Practical applications
Why structural reporting rules make estimates necessary
In the DACH private market, key financial metrics are often missing precisely where investors need them most. Small GmbHs (private limited companies) are not required to disclose their revenue or operating profit. What appears in the Austrian company register (Firmenbuch) is often just an abridged balance sheet – with no profit and loss account or operating metrics, and sometimes up to two years late. This is not a weakness of data collection but a structural feature of the DACH private market, and it affects anyone who wants to systematically classify, compare or value unlisted companies.
How does ProxDeal reliably assess a company’s actual size and EBIT?
ProxDeal addresses this reality with proprietary machine learning models trained in-house, based on financial data from more than 3 million annual financial statements covering the last three years. What sets the model apart from the alternatives is the depth of company information it was trained on: detailed business model classifications across 12 dimensions, AI-powered company type analyses, and labels for business model, industry positioning and corporate structure that go far beyond standard WZ industry codes (the German, NACE-based industry classification). The result is three key metrics per company: revenue, EBIT and employee count.
This article explains how these estimates are calculated, what they tell you and how to read them correctly without falling into common interpretation pitfalls.
Reported values first, modelling only where needed
All three estimates follow the same basic principle: if a value can be derived directly from the annual financial statements, it is used unchanged and labelled ORIG. In this case, Confidence=1.0 and P10 = P50 = P90 = the actual reported value, because no estimation interval is needed. The model only steps in when the available data does not allow a direct derivation, and it communicates this difference transparently through confidence labels. Estimates are updated every three months and always carry metadata on the data source and confidence, so that every figure remains traceable.
Modelling with machine learning
Revenue
The revenue model uses a CatBoost MultiQuantile Regressor trained on actual financial data from the DACH region. Its inputs include balance sheet items such as total assets, fixed assets, liabilities and equity, supplemented by employee numbers where available, WZ2025 industry codes and structural company characteristics, such as whether a company is a holding company or a manufacturing business.
Estimating revenue from balance sheet data is methodologically demanding, because the relationship between balance sheet size and revenue depends heavily on the industry. A retailer with total assets of €5m can generate revenue of €80m, while a holding company with total assets of €500m may report revenue of only €1m. A simple model would fail systematically here. ProxDeal solves this by combining industry codes and company type flags with net income as an additional signal, which on its own accounts for around 7% of the model weighting. The strongest predictors are total assets (21%), provisions (15%) and current assets (14%), which together capture a company’s operational complexity far better than total assets alone.
The model only runs if at least three of the seven key features are available. If too much input data is missing, no estimate is produced, because a methodologically unreliable figure is worse than no figure at all.
EBIT
For EBIT, ProxDeal follows a three-tier approach that automatically adapts to the available data. The basic rule is: the more profit and loss data is available, the more precise the estimate. If net income and at least one adjustment item, such as tax or interest payments, are available, EBIT is calculated directly and reported as ORIG with a confidence of 1.0. In this case, P10, P50 and P90 are identical, as no estimation interval is needed.
EBIT = net income + tax payments − tax refunds + interest payments − interest income
Methodological note on this formula: the calculation is deliberately limited to the two most material and universally reported adjustment items – income taxes and net interest – because these are available in almost all DACH annual financial statements that include profit and loss data. For companies with significant investment income or other financial results (particularly holding and investment structures), the reported EBIT therefore reflects the operating result. For group valuations, we recommend also consulting the consolidated financial statements.
If only net income is available without any adjustment items, which is the case for around 60% of German companies, the ML model draws on the typical tax and interest add-backs learned during training and adds them to net income. This is methodologically cleaner than simply equating EBIT with net income, because taxes and interest usually represent positive adjustments in an operating business, and ignoring them would systematically underestimate EBIT in the majority of cases. From the training dataset, the model learns not only the typical magnitude but also the sign of these adjustments – for cash-rich holding companies with positive net interest income, or in loss-making situations with tax refunds, the add-backs are modelled with the opposite sign accordingly.
If net income is missing entirely, the model estimates the EBIT margin based on the available balance sheet figures and information from the company profile (business model, industry, etc.) and calculates an EBIT value from it. This applies to around 95% of entries in the Austrian company register and around 40% of German companies. In this mode, the intervals are naturally wider, which is directly reflected in the confidence score. With a model weighting of 54%, net income is by far the strongest predictor, followed by total assets at 25%, which provides the primary signal for the balance-sheet-only path.
Employee count
The employee count is estimated using a CatBoost regression model trained on the same balance sheet metrics. The output is both a numerical estimate and a size class in ten categories, ranging from ‘2–5’ to ‘5,000+’. The model runs three plausibility checks. First, a minimum threshold for total assets is required. Second, stricter requirements apply to holding companies, because their balance sheet metrics give a structurally distorted picture of the operating workforce. Third, the estimated revenue per employee is checked for plausibility: values below €8,000 or above €3m per head are flagged as implausible. These safeguards ensure that the model does not mechanically produce a figure that makes no business sense.
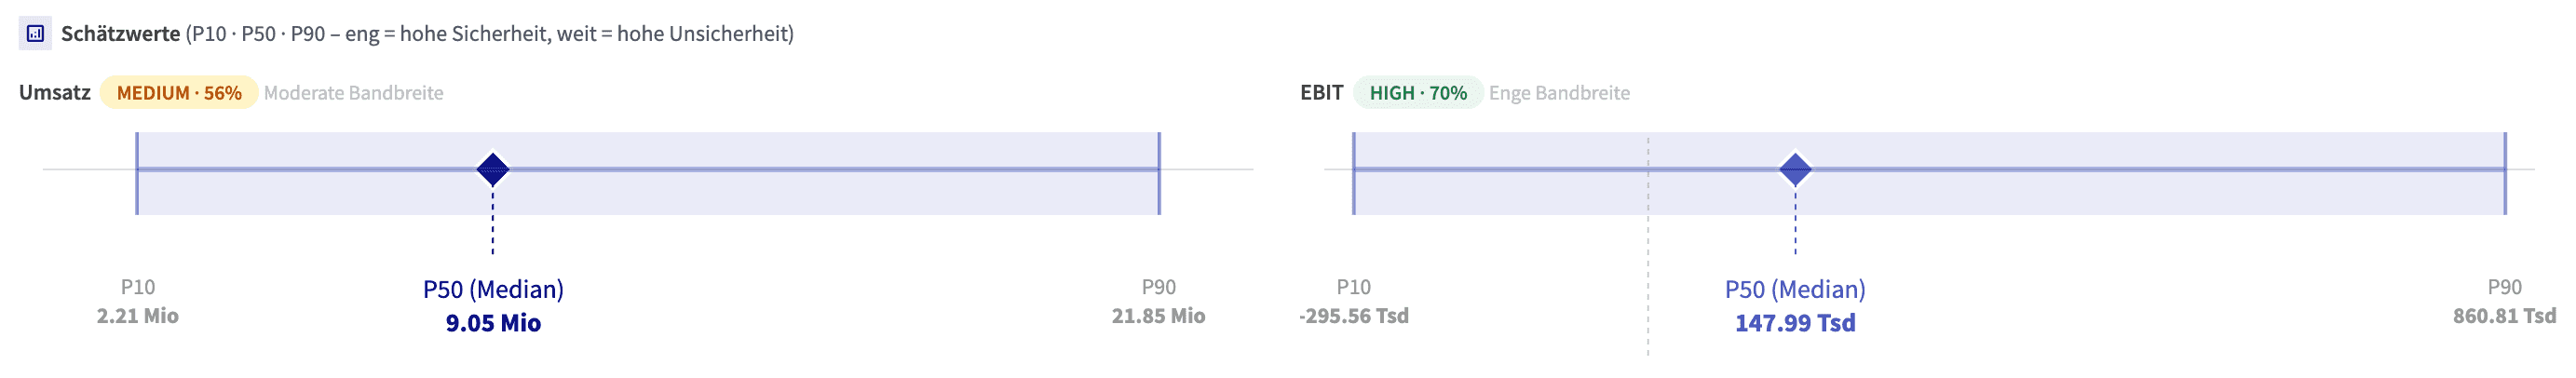
Figure 1: Visualisation from ProxDeal’s company profiles
Meaningful ranges instead of single values without context
For revenue and EBIT, ProxDeal generates three scenarios using a method called Conformalized Quantile Regression (CQR). The model first outputs raw quantile estimates. In a second step, these are adjusted using a separate calibration dataset that was never used in training, so that the P10–P90 range achieves a mathematically guaranteed coverage rate of 80%. In concrete terms, this means: in 80% of comparable cases, the actual value lies within the range provided, regardless of how wide or narrow that range is.
This 80% guarantee is marginal, meaning it holds on average across all revenue and EBIT estimates that ProxDeal provides. In individual subgroups, actual coverage may deviate from this: data-rich segments such as the German mechanical engineering sector stay close to the target value, while data-sparse cases such as small GmbHs without extended reporting obligations tend to fall below it. This is precisely why every estimate receives an individual confidence score. It reflects the uncertainty of the individual case, not the population average.
The confidence score – how useful is the estimate?
The confidence score is not a separate model but a direct function of the width of the range. The closer P10 and P90 are to each other, the higher the confidence. It answers the question: how actionable is this estimate for a specific decision?
Confidence | Meaning |
|---|---|
High | Narrow range, complete data. Suitable for analysing individual companies. |
Medium | Medium-width range. Suitable for portfolio and cohort analyses, not for individual decisions. |
Low | Wide range, sparse data. Use with caution; additional sources recommended. |
An important note on interpretation: a low confidence score does not mean that the range is unreliable. The 80% coverage guarantee applies regardless of the confidence score. A low score simply means that the range is so wide that, for precise modelling, it narrows things down very little in practice.
Interpretation – how to read the estimates correctly
The most common mistake when working with statistical estimates is to treat the median (P50) as a fact. P50 is the median of the model distribution: the value that splits the estimated probability mass in half. It is the most robust single figure for comparisons and initial assessment – but it remains an estimate, not a measurement. We report the median rather than the mean because it is robust to outliers in the distribution and, for right-skewed variables such as revenue and EBIT, represents the typical company better than the mean, which is distorted by a small number of large companies. Together, the trio of P10, P50 and P90 describes what the model knows about a company – and what it does not.
The right starting point is always the median (P50). It is the value you should use for comparisons, longlist screenings and initial valuation assessments. For most applications, P50 is sufficient.
P10 and P90 become relevant as soon as a decision is sensitive to the actual value. The key question is then not ‘What is the most likely value?’ but ‘What happens if the actual value lies at the lower or upper end?’ For an acquisition: Does the investment still hold up if actual revenue is closer to P10 than to P50? For lending: Is debt service still covered if EBIT is closer to P10? Conversely, P90 is useful when you want to assess a company’s upside potential, for example for growth financing or market potential analyses.
The width of the range is itself informative. A narrow P10–P90 range means that the ML model can assess the company accurately, because the data is dense enough to meaningfully narrow down the possible values. A wide range is not an error but an honest statement: the model has too little signal to be more precise. In this case, the estimate should be used as a rough guide rather than as a reliable point estimate.
An important point about the statistical guarantee: the P10–P90 range has a mathematically calibrated coverage rate of 80%. This means that in 80% of comparable cases, the actual value lies within this range, regardless of how wide or narrow it is. A company with a range of €0.4m to €38m has the same statistical coverage as one with a range of €38m to €52m. The difference lies solely in precision, not in reliability.
Practical applications
Buy-side M&A. Before due diligence, P50 revenue gives you an initial sense of scale that enables comparisons within a longlist without an analyst having to research every company manually. P10 EBIT shows whether the investment still holds up in a conservative scenario.
Distressed M&A. For companies with limited data, the estimates provide a structured basis for purchase price considerations. A wide P10–P90 range combined with a high insolvency risk is a clear signal that more extensive due diligence is required.
Market and competitive analysis. For investors systematically screening an industry or region, the estimates enable quantitative comparisons even where no published revenue figures are available. P90 revenue indicates the upper end of the range among market participants.
ProxDeal’s financial estimates do not deliver certainty, but something more valuable: a structured, transparent basis for decisions that would otherwise rest on gut feeling or missing data.
Stay ahead
 Stay ahead
Discover what ProxDeal PRO can do.
ProxDeal is built specifically for the DACH M&A market. Give yourself a decisive competitive edge – starting today.
Related articles
Market Analysis
Insolvency risk analysis in the DACH private market
How can you make a reliable assessment of insolvency risk when only a limited set of financial metrics is available?
Company Database
What sets ProxDeal apart from traditional databases
AI-powered M&A company search in Germany.
Company Database
Swiss company data: how ProxDeal creates transparency
Questions and answers on the data landscape of the Swiss company market.